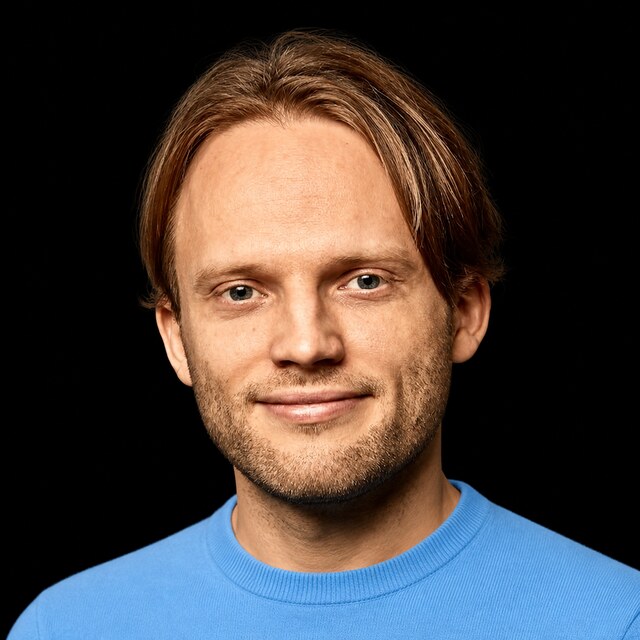
Jan Leike 🇩🇪
Machine-learning and alignment researcher working on scalable oversight, robustness, and systems that follow human intent beyond direct evaluation.
Anthropic
- Evidence items
- 4
- Toward pressure
- +0.22
- Away pressure
- −0.08
- Net attributed pressure
- +0.14
0 comments · 0 votes
Sign in to join the discussion →
No comments yet. Start the discussion.
Videos featuring or explaining Jan Leike
Reviewed videos from Artificial Intelligence Videos. These links add context and never change a DoomBench score.
Current and former organisations
These dated, source-backed roles support navigation between people and companies. They do not attribute a story or change the Doom Index.
First-person and official sources
These sources guide discovery. A statement still needs a dated, attributable, source-backed evidence assessment before it can affect the index.
- personal siteJan Leike
Assessments involving Jan Leike
Anthropic reports production safety training that suppresses agentic misalignment
Anthropic reported that difficult-advice training reduced agentic misalignment to zero in its evaluation and that constitution-based documents generalized beyond their training distribution. The techniques were applied to production models beginning with Claude Opus 4.5, with explicit warnings that the tests cannot guarantee safety.
Jan Leike says recursive AI self-improvement has begun in alignment research
Jan Leike wrote that Claude was producing almost all of his team's research code, mostly autonomously running standard sampling, evaluation, and fine-tuning workflows, auditing models, and reading transcripts. He called this the start of recursive self-improvement, while arguing alignment looks increasingly solvable and warning that faster automated research may leave little time to align superintelligence.
Jan Leike identifies self-exfiltration as a key AI control threshold
Jan Leike argues that a model able to copy its own weights beyond an operator's servers could become practically irrecoverable, making self-exfiltration capability a critical safety and deployment threshold.
DeepMind and OpenAI demonstrate reinforcement learning from human preferences
DeepMind and OpenAI researchers showed that reinforcement-learning agents could learn complex behavior from sparse human preference comparisons, using roughly 900 bits of feedback for a simulated backflip and reaching superhuman Atari performance. The work documented reward-hacking limits while establishing a practical technique later deployed in instruction-following language models.